Reliability & infrastructure · remote

Your product shouldn't go down
because nobody was watching.

I'm Hossam Alnemr. I run production infrastructure for software teams that don't have an infrastructure person — monitoring that actually pages someone, deployments that don't break on Fridays, and cloud bills that stop climbing.

Currently responsible for production across five companies on AWS, GCP, Hetzner and Oracle Cloud — including a financial-services environment under regulatory audit.

Who this is for

I'd rather tell you now than waste a call.

This is for you if

  • You have roughly 5–30 engineers and nobody actually owns infrastructure
  • Deploys are manual, or exactly one person knows how to do them
  • You found out you were down from a customer, not from an alert
  • Your cloud bill grows every month and nobody can explain why
  • You need a person who is accountable at 3am — not another dashboard

Probably not a fit if

  • You already have a platform or SRE team — you don't need me
  • You want application code written; I don't build product features
  • You need someone on site full time
  • You want the cheapest option rather than the one that stops the bleeding

Three ways to start

Fixed scope, written deliverables, no open-ended hourly billing. Every engagement is quoted in writing after the free check, once I know what I am actually looking at — so the number reflects your setup, not an average.

One-off

Reliability audit

Fixed price, quoted after the free check · about one week

A full read of your production setup, written down in plain language your CTO and your CEO can both act on.

  • Every single point of failure, ranked by what it would cost you
  • Backups tested by actually restoring them, not by reading the config
  • Cloud spend broken down with the waste named
  • A prioritised fix list you can hand to anyone
Subscription

Uptime & certificate watch

Per site, billed monthly · cancel any time

The smallest useful thing I sell. If your site, API or certificate breaks, you hear it from me first.

  • Uptime, response time and full certificate-chain checks
  • Warnings 30 days before a certificate expires
  • Alerts on WhatsApp, Telegram, Slack or email — your choice
  • A one-page monthly summary

What I'm running right now

Not a certificate collection — production systems that people depend on today.

Production estates under my responsibility

5

Clouds in daily use

4

AWS · GCP · Hetzner · OCI

Alert rules I install as standard

32

hosts · containers · DB · TLS

Dashboards ready on day one

7

Grafana, pre-built

Kubernetes and GKE · Jenkins and GitHub Actions · Terraform · Prometheus, Grafana and Loki · MongoDB, PostgreSQL and Redis · Laravel, Odoo and Node in production · regulated environments with audited access controls.

Why monitoring is the first thing I install

One Saturday made this non-negotiable.

A client's production went down on a weekend. It wasn't a bug, it wasn't traffic, and it wasn't a bad deploy. A TLS certificate had quietly expired. Every server was healthy, every service was running — and every customer got a browser security warning instead of a checkout page.

The renewal had always been manual, and the person who used to do it had moved on. Nobody was watching that one number, so nobody knew until revenue stopped.

So I built the thing that makes it impossible to repeat, and now every environment I take on gets it in the first week — certificate expiry watched continuously, 30 days of warning before anything breaks, and renewal automated wherever the DNS provider allows it. Same story for disks filling up, queues backing up, and backups that silently stopped running three months ago.

Almost every outage I've been called into was something ordinary that nobody was looking at.
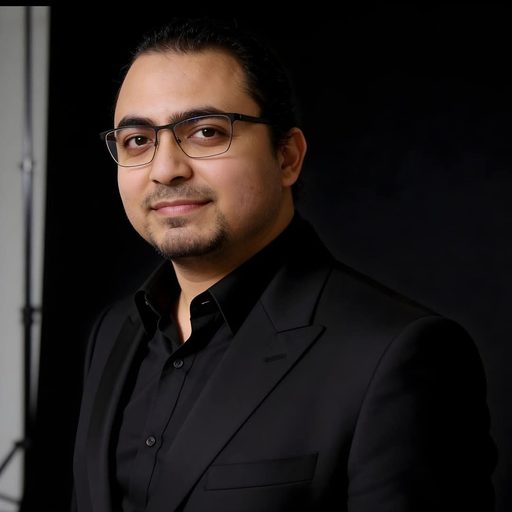
Who you would actually be working with

No account manager, no handover, no junior doing the work behind the logo.

Hossam Alnemr

Hossam Alnemr

Infrastructure & reliability · Cairo, GMT+2

I have spent my career keeping other people's production running — across AWS, GCP, Hetzner and Oracle Cloud, in environments ranging from a fast-moving delivery platform to a financial-services estate under regulatory audit. Kubernetes, CI/CD, monitoring, certificates, backups, cloud spend: the unglamorous layer your product sits on.

Alnemr Reliability is me. I am not a reseller and there is no team behind a logo — when something breaks at 3am, the person who answers is the same person who built it. That is the entire point. When a job needs hands I do not have, I say so and bring in someone I have worked with, in the open.

How starting works

No access, no contract and no commitment until step three.

1

Free reliability check

I look at what's already public: certificates, security headers, DNS, response times, exposed services. Takes me 15 minutes and needs nothing from you. You get the findings either way — even if we never speak again.

2

A 20-minute call

We go through what I found and what's actually hurting you. If I'm not the right person for it, I'll say so on the call and point you somewhere better.

3

Audit or retainer

Fixed scope and a fixed price, agreed in writing before anything starts. Most teams begin with the audit, then move to a monthly retainer once they can see what they were missing.

Tell me what's breaking

I read every message myself and reply within one working day — usually with something useful whether or not you hire me. Pick whichever is easiest.

or send it here

Questions people actually ask

Do you need access to our production systems?

Not to begin with. The free check uses only what's publicly visible. When we do start, I work with the narrowest access that gets the job done, from a fixed IP address you can allowlist, and I'm happy to work inside your VPN rather than around it.

Where are you, and what hours do you cover?

Cairo, GMT+2 — which overlaps the full working day in Saudi Arabia, the UAE and Europe. Retainers include agreed escalation hours; genuine production emergencies are covered outside them.

Will you sign an NDA?

Yes, before anything technical is discussed. I already work inside environments subject to financial-sector regulation, so strict access rules and audit trails are normal for me, not an obstacle.

We already have monitoring. Is this still useful?

Often, yes — most teams have dashboards nobody looks at rather than alerts that reach a human. The question isn't whether metrics are being collected; it's whether someone's phone rings at 3am, and whether the alert says what to do. That's usually the gap.

How do we pay, and in what currency?

Bank transfer or Wise for audits and retainers, invoiced in USD; the monthly subscription can go on a card. Retainers are month to month — 30 days' notice, no annual lock-in.